
Why PDB Annotations Fail Cancer Gene Research and How to Fix Them
Protein Data Bank (PDB) annotations often contain silent errors, undeclared mutations, and sequence mismatches that compromise structural biology. These flaws make deposited structures unreliable for cancer gene research. Morphogenesis Analytics provides a computational audit that flags these discrepancies at the residue level. This process ensures that structural data reflects the true biological state of the protein before it is used in downstream analysis. according to Understanding the impacts For additional details, review the .
The Hidden Flaws in Structural Deposits
Researchers frequently assume that a deposited structure perfectly matches its declared mutation labels. In reality, the Protein Data Bank is a repository of experimental snapshots, not a curated database of perfect biological states. A structure may be labeled as a specific mutant, but the actual sequence in the file might contain additional, undeclared substitutions. These silent errors can arise from cloning artifacts, construct variations, or simple metadata mistakes during the deposition process. according to Nonsynonymous synonymous and
Identifying these flaws requires a systematic comparison between the declared metadata and the actual atomic coordinates. Without this check, researchers risk building their entire analysis on a flawed foundation. The implication is clear: structural data must be validated before it is trusted for precision oncology or drug discovery.
Sequence Identity vs. Structural Geometry
Sequence identity is the comparison of amino acid residues between two protein structures. Structural geometry is the three-dimensional arrangement of those residues in space. These two metrics are distinct and often contradictory. A structure can have 99% sequence identity to a reference but a significantly different geometry due to conformational changes, ligand binding, or crystal packing effects.
Conversely, two structures with lower sequence identity might share a nearly identical core geometry if the mutations occur in flexible loops or peripheral domains. Relying on sequence identity alone to determine if two structures are comparable is a common pitfall. Researchers must separate these evidence layers. Geometry describes the shape, while sequence describes the composition. Treating them as interchangeable leads to incorrect conclusions about mutation impact. according to R Percent Sequence
For example, a mutation in a flexible loop might not change the overall fold, but it could disrupt a transient interaction. A structural comparison that ignores this distinction will miss the functional consequence. By analyzing geometry and sequence separately, researchers can identify which differences are structural and which are compositional. This separation is essential for accurate interpretation of cancer gene variants. according to Understanding oncogenicity of
The Problem of Undeclared Mutations
Undeclared mutations are substitutions present in the deposited structure but not listed in the PDB header or associated metadata. These are the most dangerous type of annotation error because they are invisible to standard database queries. A researcher searching for a specific mutant will retrieve the structure, assuming it is the correct variant. However, the actual sequence may contain additional changes that alter the protein's behavior. according to Mutational heterogeneity in
These hidden mutations can arise from several sources. Cloning vectors may introduce silent mutations or frame shifts. Expression constructs might contain tags or linkers that are not fully removed. In some cases, the mutation of interest may not have been successfully introduced, resulting in a wild-type structure labeled as a mutant. Each of these scenarios produces a structure that does not match its label.
The implication for cancer research is severe. If a structure is used to study the mechanism of a specific oncogenic mutation, but it actually contains a different mutation, the resulting model will be incorrect. This can lead to failed drug binding predictions or misidentified binding sites. Detecting these undeclared mutations requires a residue-level audit of every deposited structure. This is where specialized computational tools become essential.
How Computational Audits Fix Annotation Errors
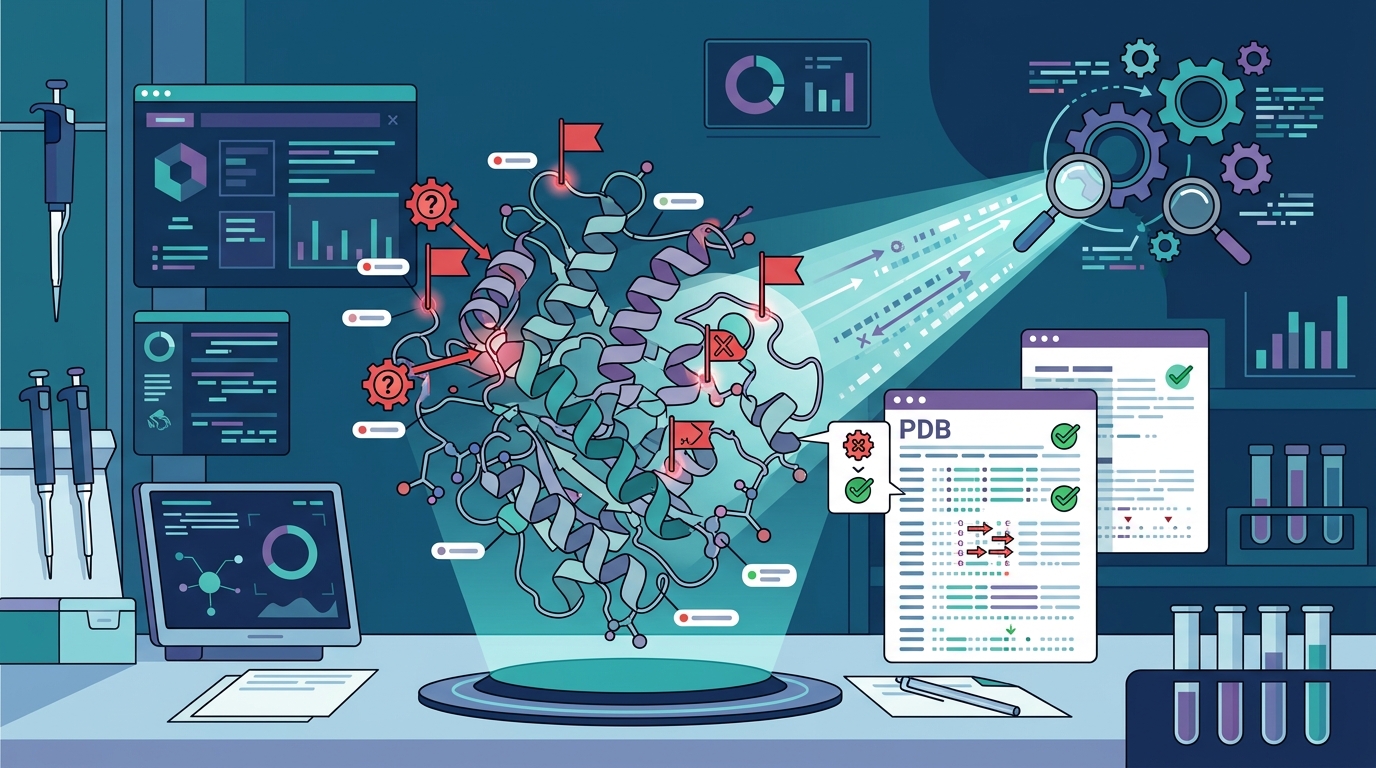
A computational audit is a systematic process that compares the declared metadata of a PDB entry against its actual atomic coordinates. This process identifies discrepancies in sequence, mutation labels, and structural geometry. The output is a flagged report that highlights every residue where the structure does not match the expected reference. This report provides the evidence needed to determine if a structure is usable for a specific research question.
The audit process involves several key steps. First, the sequence of the deposited structure is extracted and compared to the reference sequence. Second, any mutations declared in the metadata are verified against the actual residues. Third, the structural geometry is compared to a reference structure to identify conformational differences. Each of these steps produces a distinct layer of evidence. The final report combines these layers to provide a comprehensive view of the structure's reliability.
For researchers, this audit transforms a potentially flawed data point into a validated resource. It allows them to make informed decisions about which structures to use in their analysis. The implication is a higher level of confidence in the results. By using audited structures, researchers can avoid the pitfalls of silent annotation errors and build more robust models of cancer gene function.
Practical Steps for Reliable Structural Analysis
Researchers can improve the reliability of their structural analysis by following a few practical steps. First, always verify the sequence of a deposited structure against the reference. Do not assume that the metadata is accurate. Second, use a computational tool to perform a residue-level audit. This will identify any undeclared mutations or sequence mismatches. Third, separate the evidence layers. Analyze geometry and sequence independently to understand the source of any differences. according to Locus Specific Databases
Second, consider the context of the structure. Crystal structures are snapshots of a specific conformation, often influenced by crystal packing. Solution structures, such as those from NMR or cryo-EM, may provide a more dynamic view. Understanding the experimental method helps interpret the structural differences. Third, document your audit process. Keep a record of which structures were used, what discrepancies were found, and how they were resolved. This documentation is essential for reproducibility and peer review.
By following these steps, researchers can mitigate the risks associated with PDB annotation errors. The goal is not to discard flawed structures, but to understand their limitations. A structure with a known, documented discrepancy can still be valuable if the researcher accounts for it in their analysis. The key is to be aware of the potential errors and to use the right tools to identify them.
Key Takeaways
- PDB annotations often contain silent errors, including undeclared mutations and sequence mismatches.
- Sequence identity and structural geometry are distinct metrics that must be analyzed separately.
- Undeclared mutations can arise from cloning artifacts, construct variations, or metadata mistakes.
- Computational audits provide a residue-level check of deposited structures against reference sequences.
- Separating evidence layers (geometry, sequence, labels) is essential for accurate interpretation.
- Documenting the audit process is critical for reproducibility and peer review.
- Using audited structures increases confidence in downstream analysis and drug binding predictions.
Frequently Asked Questions
What is a PDB annotation error?
Why are undeclared mutations dangerous for cancer research?
Undeclared mutations can alter the protein's conformation or binding affinity. If a structure is used to study a specific mutation but contains a different one, the resulting model will be incorrect.
How does a computational audit work?
A computational audit compares the declared metadata of a PDB entry against its actual sequence and geometry. It identifies discrepancies at the residue level and produces a flagged report.
Can a structure with a known discrepancy still be used?
Yes, if the discrepancy is documented and accounted for in the analysis. The key is to be aware of the error and to interpret the results with that context in mind.
What is the difference between sequence identity and structural geometry?
Sequence identity is the comparison of amino acid residues. Structural geometry is the three-dimensional arrangement of those residues. These two metrics are distinct and often contradictory.
How can I verify the sequence of a deposited structure?
You can use a computational tool to extract the sequence from the PDB file and compare it to the reference sequence. This will identify any mismatches or undeclared mutations.
Conclusion
Reliable structural analysis requires a rigorous approach to data validation. PDB annotations are not infallible, and silent errors can compromise the integrity of cancer gene research. By using computational audits to identify and document these discrepancies, researchers can build more robust models and make better-informed decisions. Morphogenesis Analytics provides the tools and expertise to perform these audits, ensuring that your structural data is as reliable as your scientific questions. To begin your structural audit, visit the Morphogenesis Analytics platform. according to Comparison of Fresh