
Skills You Will Build Using Protein Structure Analyzer Over a Semester
Using the Protein Structure Analyzer over a semester develops practical skills in structural data auditing, mutation validation, and comparative geometry. Students learn to distinguish geometric differences from biological function while managing distinct evidence layers. This hands-on experience builds the critical thinking required for rigorous computational biology research.
Structural Data Auditing and Identity Verification
One of the first skills you will master is structural identity verification. Structure identity audit is the process of confirming that a deposited protein entry matches the intended gene, chain, and domain. When you submit a list of PDB IDs to the platform, you learn to read the flagged CSV output. This output provides residue-level evidence for sequence differences. You will quickly notice that mutation labels in public databases are not always accurate. The tool helps you identify undeclared mutations and wrong domains. This skill is essential for anyone working with structural data. It prevents you from building models on incorrect foundations.
Mutation Structural Checks and Evidence Layers
As you progress, you will develop expertise in mutation structural checks. Mutation structural check is the analysis of a named substitution against every matching deposited structure. You will learn to interpret per-residue displacement data. This involves comparing mutant and wildtype structures region by region. A key part of this skill is understanding evidence layers. Geometry, sequence identity, and deposited mutation labels are distinct kinds of evidence. The platform reports these separately. You will also see AlphaMissense scores alongside your results. It is important to remember that these are third-party predictions. They are not generated by the platform. Learning to separate these layers prevents misinterpretation of your data.
Pairwise and Cross-Family Comparative Analysis
By the middle of the semester, you will be ready for more complex comparisons. Pairwise structure comparison is the region-by-region analysis of two structures of the same protein. You might compare two drug-bound states or a mutant against a wildtype. This skill requires you to understand conformational states. Differences can arise from ligands or binding partners. You will also learn cross-family comparison. This involves looking at structural variation across several cancer gene families. The aggregate report helps you see patterns that single-structure analysis misses. This broadens your perspective from single molecules to family-level trends.
Predicted Model Cleanup and Regularization
In the later stages, you will tackle predicted model cleanup. Backbone-spacing regularization is the process of refining AlphaFold-style models to correct spacing issues. You will learn to identify and fix geometric artifacts in predicted structures. The platform returns a refined PDB file. This is a practical skill for anyone working with predicted models. It teaches you to trust the geometry while remaining critical of the prediction. You will understand that a clean backbone does not guarantee biological accuracy. This nuance is a hallmark of advanced computational biology training.
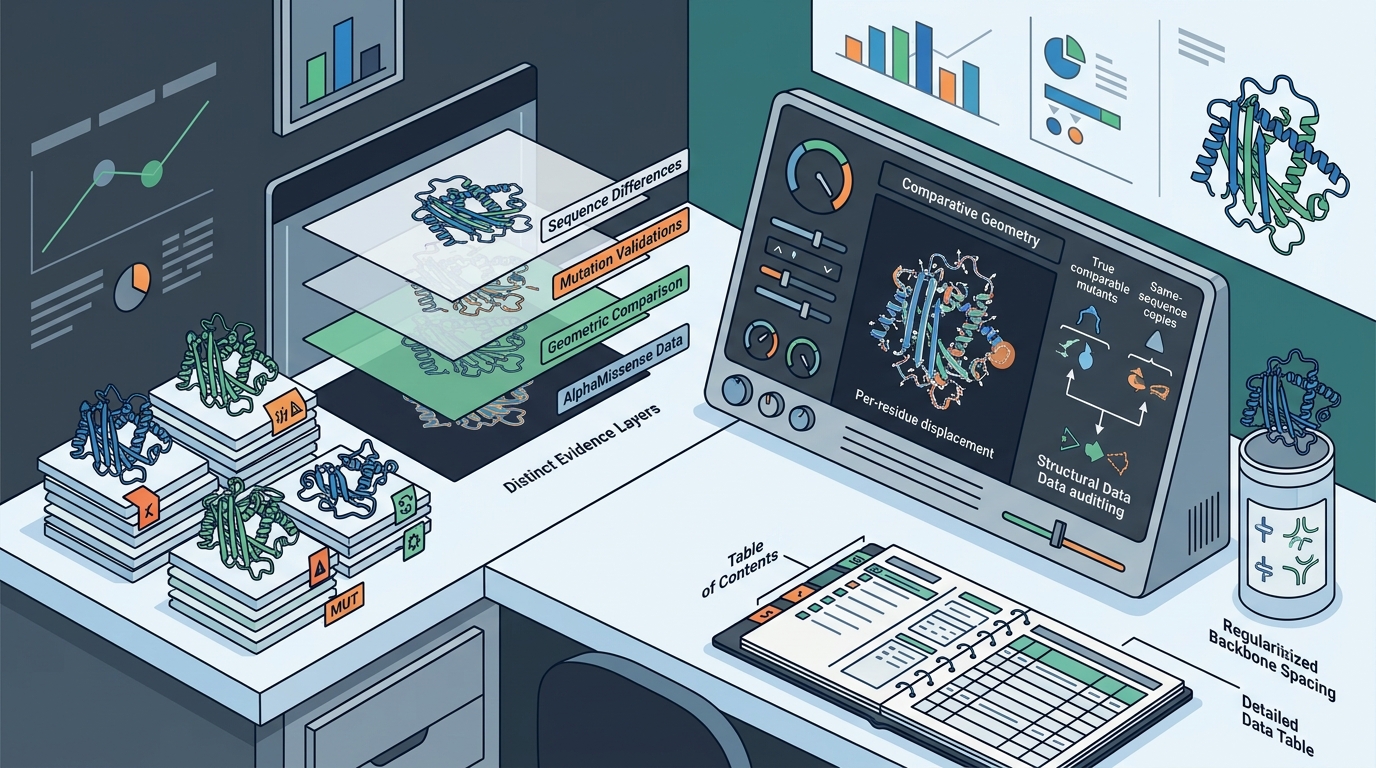
Writing Evidence-Based Research Briefs
Key Takeaways
- You will learn to audit structural data for identity and sequence discrepancies.
- You will master the separation of distinct evidence layers in mutation analysis.
- You will gain experience in pairwise and cross-family structural comparisons.
- You will develop skills in refining predicted models using backbone regularization.
- You will learn to write clear, evidence-based research briefs from computational data. according to Data Analysis Tools
- You will understand the limitations of structural distance as a measure of biological function.
Frequently Asked Questions
What is the primary skill developed in the first month?
The primary skill is structural identity auditing. You learn to verify that deposited entries match the intended protein and domain.
How does the tool handle mutation labels?
The tool flags discrepancies between declared mutation labels and actual sequence differences. It provides residue-level evidence for these flags.
Are AlphaMissense scores generated by the platform?
No. AlphaMissense scores are third-party predictions. They are shown alongside the platform's results as a separate layer.
What is the difference between geometric difference and biological function?
Geometric difference describes the physical distance between structures. It does not indicate biological function, pathogenicity, or drug sensitivity.
Can I use the results for clinical decisions?
No. The platform is for research use only. It is not a medical device or clinical diagnostic tool. according to Data Analysis Tools
What is a research brief in this context?
A research brief is a written evidence summary built from the platform's analysis runs. It synthesizes findings from multiple data types. according to Study Applied Statistics
Conclusion
Using the Protein Structure Analyzer over a semester provides a robust foundation in computational structural biology. You will move from basic data auditing to complex comparative analysis and model refinement. Morphogenesis Analytics provides the tools to make these skills tangible. By the end of the semester, you will be able to interpret structural data with confidence and nuance. You will understand the limitations of your tools and the importance of evidence layers. This preparation is invaluable for a career in biotech or academic research. Start your journey today and build the skills that will define your expertise.