
How to Detect Undeclared Mutations in PDB Entries
Undeclared mutations in PDB entries are a critical data integrity issue for structural biology. You can identify them by comparing the deposited sequence against a reference wild-type sequence and analyzing geometric deviations. Morphogenesis Analytics provides a specialized Protein Structure Analyzer that automates this audit. This guide explains how to detect hidden mutations, validate structural data, and interpret the results accurately for research purposes.
Introduction to Structural Data Integrity
Protein Data Bank (PDB) entries are the foundation of structural biology research. However, the metadata associated with these entries, including titles and mutation labels, is not always perfectly accurate. Researchers often encounter entries where the deposited sequence contains mutations that are not explicitly mentioned in the entry title or the mutation label fields. This discrepancy can lead to misinterpretation of structural data, particularly in studies involving drug binding or protein-protein interactions. according to PDBsum For additional details, review the .
Morphogenesis Analytics addresses this challenge by providing computational tools for auditing protein structures. The platform focuses on identifying which entries represent the correct protein, chain, and domain, while flagging sequence differences that are not declared in the metadata. By automating this process, researchers can ensure that their structural analyses are based on accurate data. This guide details the methodology for detecting these undeclared mutations and interpreting the resulting evidence. For additional details, review the Customer Experience.
Engineered Mutation Detection
Engineered mutation detection is the process of identifying amino acid substitutions in a protein sequence that differ from a reference wild-type sequence. In the context of PDB entries, this involves comparing the sequence of the deposited structure against a known reference sequence. The goal is to find residues that have been changed, either intentionally for experimental purposes or due to cloning artifacts. For additional details, review the Frequently Asked Questions.
Sequence Comparison Methodology
Identifying Undeclared Mutations
Once the sequence differences are identified, the next step is to cross-reference them with the metadata provided in the PDB entry. The platform checks the entry title and the mutation label fields. If a sequence difference is found in the comparison but is not listed in the metadata, it is flagged as an undeclared mutation. This is a critical step because undeclared mutations can significantly alter the structural and functional properties of the protein. For additional details, review the About.
Deliverables and Output
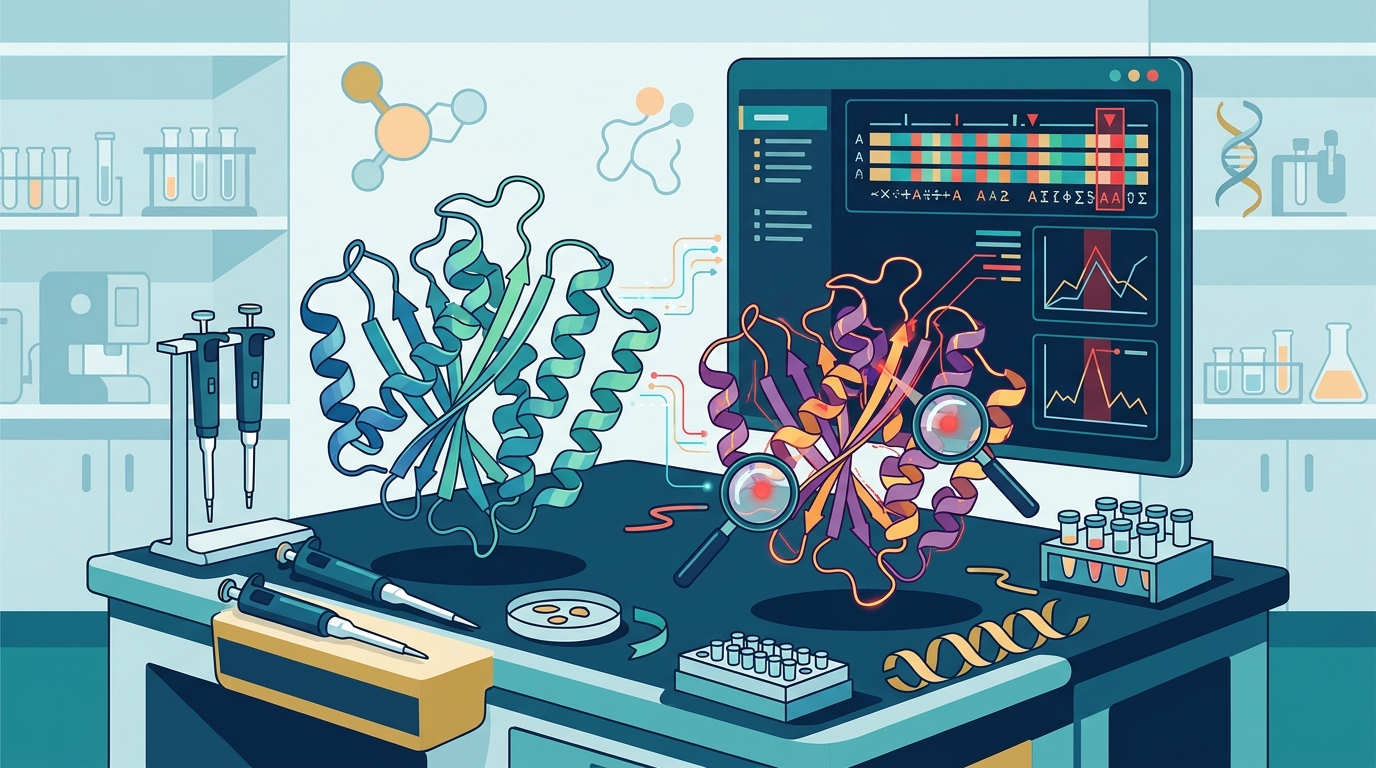
The detection process is delivered as a flagged CSV file. This file contains the residue-level evidence for each mutation, including the position, the reference amino acid, and the deposited amino acid. The CSV format allows researchers to easily import the data into their own analysis pipelines. The platform also provides a summary report that highlights the most significant discrepancies.
Understanding Evidence Layers
Interpreting structural data requires understanding the different types of evidence available. Geometry, sequence identity, deposited mutation labels, and pathogenicity annotations are distinct kinds of evidence and are reported separately. Each layer provides a different perspective on the protein structure and its potential mutations. according to Percent Identity of
Geometric Evidence
Sequence Identity
Sequence identity is the percentage of amino acids that are identical between two sequences. In the context of mutation detection, sequence identity is used to determine how closely the deposited sequence matches the reference sequence. A high sequence identity suggests that the deposited structure is likely to be the correct protein, while a low sequence identity may indicate a different protein or a significant number of mutations. according to Versor A Geometric
Deposited Mutation Labels
Deposited mutation labels are the annotations provided by the depositor in the PDB entry. These labels describe the mutations that were intentionally introduced into the protein. However, as noted earlier, these labels are not always complete or accurate. The platform compares the deposited labels with the actual sequence differences to identify any discrepancies. This comparison is essential for ensuring the accuracy of the structural data.
Interpreting Structural Distance
Structural distance from a reference describes geometric difference, not biological function, mutation impact, pathogenicity, cancer severity, or drug sensitivity. It is a measure of how far the atoms in the deposited structure are from the atoms in the reference structure. This metric is useful for identifying conformational changes, but it should not be used to infer biological significance without additional evidence.
Conformational States
Differences in structural distance can arise from conformational state, construct, ligands, or binding partners. A protein may adopt a different conformation when bound to a ligand or when interacting with another protein. These conformational changes can result in significant geometric differences, even if the amino acid sequence is identical. Therefore, structural distance must be interpreted in the context of the experimental conditions.
Ligand and Binding Partner Effects
The presence of ligands or binding partners can also affect the structural distance. Ligands can induce conformational changes in the protein, leading to geometric differences. Similarly, binding partners can stabilize certain conformations or induce changes in the protein structure. These effects must be considered when interpreting structural distance data.
Limitations of Structural Distance
It is important to recognize the limitations of structural distance as a metric. It does not provide information about the biological function of the protein or the impact of mutations. It is a purely geometric measure and should be used in conjunction with other evidence, such as sequence data and functional assays. Researchers should avoid drawing conclusions about biological significance based solely on structural distance. according to Versor A Geometric
Validation and Verification
Validation and verification are essential steps in the process of detecting undeclared mutations. Absent data, missing density, or an undeclared mutation is not a negative finding. A flagged label discrepancy should be checked against the original deposition before concluding the entry is wrong. This process ensures that the results are accurate and reliable.
Checking Original Deposition
When a label discrepancy is flagged, the first step is to check the original deposition. This involves reviewing the PDB entry and the associated publication to determine if the mutation was intentionally introduced but not labeled. In some cases, the depositor may have made an error in the labeling process. In other cases, the mutation may have been introduced as part of a cloning strategy and not considered a significant feature of the study.
Experimental Features
Independent Verification
Key Takeaways
- Undeclared mutations in PDB entries can be detected by comparing the deposited sequence against a reference wild-type sequence.
- Geometric, sequence, and label evidence are distinct and must be reported separately. according to Percent Identity of
- Structural distance measures geometric difference, not biological function or mutation impact.
- Conformational states, ligands, and binding partners can cause geometric differences without sequence changes.
- Flagged label discrepancies should be verified against the original deposition before concluding an error.
- Experimental modules have not passed validation and should not be used for critical analyses.
- Users are responsible for independent verification of results.
- Morphogenesis Analytics provides automated tools for auditing protein structures and detecting undeclared mutations.
Frequently Asked Questions
What is an undeclared mutation in a PDB entry?
An undeclared mutation is an amino acid substitution in the deposited sequence that is not mentioned in the entry title or mutation labels.
How does Morphogenesis Analytics detect undeclared mutations?
The platform compares the deposited sequence against a reference sequence and flags any differences that are not listed in the metadata.
What is the difference between geometric and sequence evidence?
Geometric evidence refers to the three-dimensional coordinates of atoms, while sequence evidence refers to the amino acid sequence. They are distinct types of data.
Can structural distance be used to determine mutation impact?
No, structural distance describes geometric difference, not biological function or mutation impact. It should not be used to infer biological significance.
What should I do if a label discrepancy is flagged?
You should check the original deposition and associated publication to verify if the mutation was intentionally introduced but not labeled.
Are experimental modules validated?
No, modules marked experimental have not passed validation and should not be used to identify drug-binding sites or other critical features.
Is Morphogenesis Analytics a medical device?
No, it is a computational analysis tool for research use only. It is not a medical device or clinical diagnostic.
Who is responsible for verifying the results?
Users are responsible for independent verification of the results. The platform provides results as is, without guarantee of accuracy or completeness.
Conclusion
Detecting undeclared mutations in PDB entries is a critical step in ensuring the accuracy of structural biology research. By using computational tools like the Protein Structure Analyzer from Morphogenesis Analytics, researchers can automate the process of identifying sequence differences and flagging metadata discrepancies. This guide has outlined the methodology for detecting these mutations, interpreting the evidence, and validating the results. Remember that structural distance and geometric evidence are distinct from biological function and mutation impact. Always verify flagged discrepancies against the original deposition and use independent methods for confirmation. Morphogenesis Analytics provides the tools you need to audit your structural data with confidence.