
Protein Structure Validation: Flagged CSVs and Residue-Level Evidence
Yes, Morphogenesis Analytics provides a service that returns a flagged CSV of PDB entries with residue-level evidence for each flag. This guide covers how structure identity audits work, how to interpret residue-level outliers, and how to use the platform for gene-family structural surveys and pairwise comparisons. It explains the difference between geometric distance and biological function, ensuring researchers understand exactly what the data represents. For additional details, review the Protein Structure Analyzer.
Structure Identity and Label Audit
Protein structure validation is the process of verifying that a deposited PDB entry matches its declared gene, chain, and domain identity. Morphogenesis Analytics automates this audit by taking a gene name or a list of PDB IDs and returning a flagged CSV. The output identifies which entries are the correct protein and which contain sequence differences that their mutation labels do not declare. This is critical for researchers building datasets for machine learning or structural biology studies. according to Protein Data Bank For additional details, review the .
Residue-Level Evidence
Each flag in the CSV is supported by residue-level evidence. The platform compares the deposited sequence against the reference gene sequence. If a discrepancy is found, the report specifies the exact residue positions and the nature of the difference. This level of detail allows users to distinguish between true mutations, construct artifacts, and labeling errors. The evidence is delivered in a format that can be directly imported into analysis pipelines. For additional details, review the Customer Experience.
Why Labels Fail
Deposited mutation labels are often incomplete or incorrect. A structure may be labeled as a wild-type protein but contain a silent mutation or a construct-specific change. Conversely, a labeled mutant may have a different sequence than expected. The audit process flags these discrepancies, providing a clean dataset for downstream analysis. Users can filter the CSV to isolate only the entries that pass the identity check. For additional details, review the Frequently Asked Questions.
Gene-Family Structural Surveys
Separating Mutants from Copies
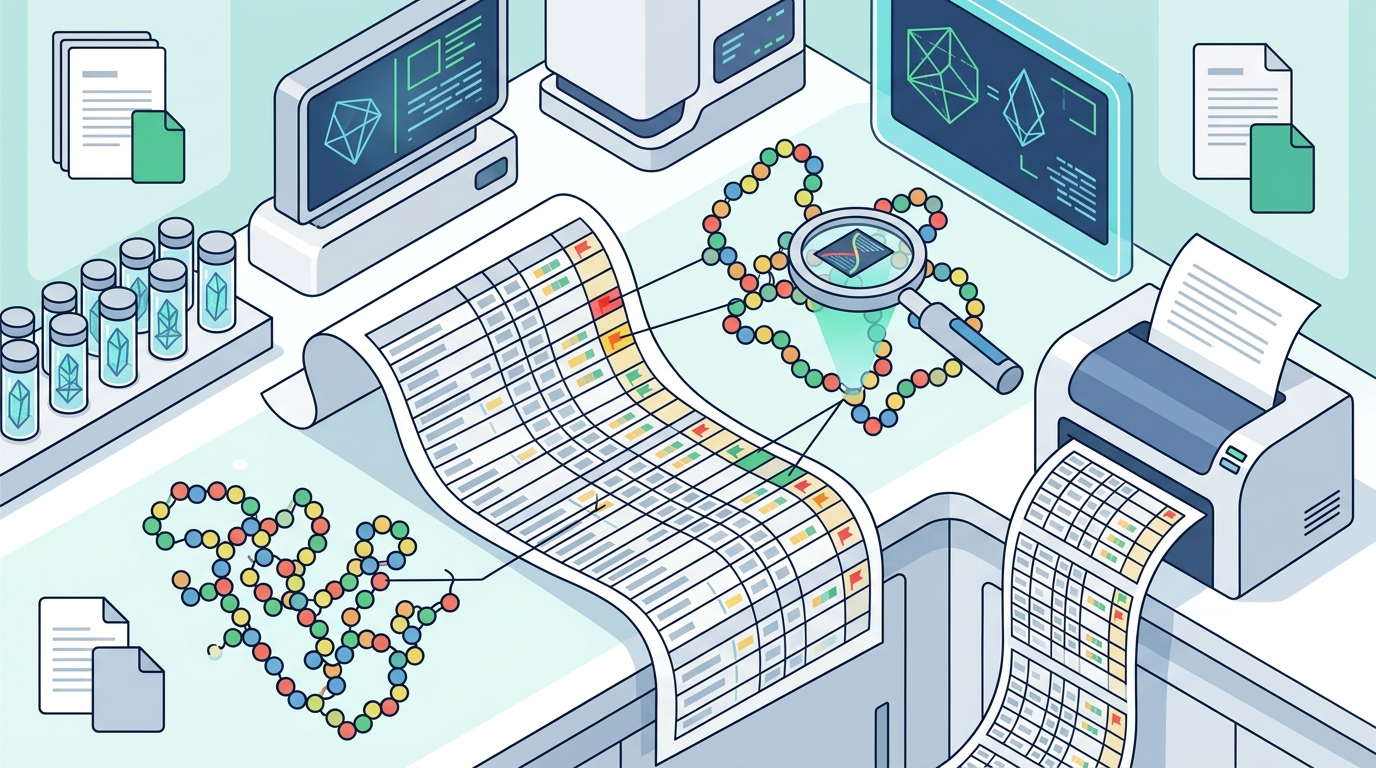
One of the challenges in structural biology is distinguishing between unique mutants and redundant copies. The survey identifies structures that are true mutants by comparing their sequences and geometries. Same-sequence copies are grouped together, reducing redundancy in the dataset. Wrong domains and partner proteins are excluded from the main analysis, ensuring that the survey focuses on the target protein. This curation step is essential for accurate statistical analysis. For additional details, review the About.
Reference-Based Measurement
Pairwise Structure Comparison
Pairwise structure comparison is the process of comparing two structures of the same protein, such as a mutant versus wild-type or two drug-bound states. Morphogenesis Analytics performs this comparison region by region, providing per-residue displacement data. The output is a comparison report that highlights the specific regions where the structures differ. This is useful for understanding how a mutation or ligand binding affects protein conformation.
Per-Residue Displacement
Drug-Bound States
Mutation Structural Checks
AlphaMissense Integration
Structural Impact
Predicted-Model Cleanup
Predicted-model cleanup is a service that refines AlphaFold-style models by applying backbone-spacing regularization. The platform takes a predicted model and returns a refined PDB file. This process improves the geometric quality of the model, making it more suitable for downstream analysis. The refinement is based on physical constraints, ensuring that the resulting model is structurally plausible.
Backbone Spacing
Backbone spacing is a key metric in protein structure validation. Predicted models often have irregular backbone spacing, which can indicate errors in the prediction. The cleanup service regularizes this spacing, producing a model with more consistent geometry. This is particularly useful for models with low confidence scores. The refined PDB file is ready for use in docking, dynamics, or other structural analyses.
Experimental Features
Some modules, such as Void Shell, are marked as experimental. These modules have not passed validation and should not be used to identify drug-binding sites. Users should be aware of the experimental status of any module they use. The platform clearly labels experimental features in its documentation. This ensures that users do not rely on unvalidated methods for critical decisions.
Cross-Family Comparison
Aggregate Metrics
Research Applications
Cross-family comparison is useful for identifying new targets for drug development. Families with high structural diversity may be more challenging to target, while those with low diversity may be more amenable to drug design. The report provides the data needed to make these assessments. It is a valuable tool for strategic planning in cancer research.
Custom Analysis and Research Briefs
Custom analysis and research briefs are written evidence briefs on a specific target or question. These briefs are built from the platform's runs and provide a narrative summary of the findings. They are useful for communicating results to non-technical stakeholders or for inclusion in grant applications. The briefs are tailored to the specific question asked, providing a focused and concise summary of the data.
Evidence-Based Writing
Deliverables
Key Takeaways
- Morphogenesis Analytics provides a flagged CSV of PDB entries with residue-level evidence for each flag.
- Structure identity audits verify that deposited PDB entries match their declared gene and domain identity.
- Gene-family structural surveys measure every deposited structure for a cancer gene against a reference.
- Pairwise structure comparison provides per-residue displacement data for two structures of the same protein.
- Predicted-model cleanup refines AlphaFold-style models by applying backbone-spacing regularization.
- Cross-family comparison provides an aggregate report on structural variation across several cancer gene families.
- Custom analysis and research briefs provide written evidence briefs on a specific target or question.
Frequently Asked Questions
What is a flagged CSV in the context of protein structure analysis?
A flagged CSV is a data file that lists PDB entries with specific flags indicating issues such as sequence discrepancies or labeling errors. Each flag is supported by residue-level evidence, allowing users to verify the findings.
How does the platform handle AlphaMissense scores?
Can the platform be used for clinical diagnostics?
No, Morphogenesis Analytics is not a medical device or clinical diagnostic. It provides computational analysis of publicly deposited protein structures for research use only. It must not be used for patient care decisions.
What is the difference between geometric distance and biological function?
Geometric distance describes the physical difference between two structures. It does not indicate biological function, mutation impact, pathogenicity, cancer severity, or drug sensitivity. Differences can arise from conformational state, construct, ligands, or binding partners.
How are experimental features labeled?
Modules marked as experimental, such as Void Shell, are clearly labeled in the platform's documentation. These modules have not passed validation and should not be used to identify drug-binding sites.
What is the output of a gene-family structural survey?
The output of a gene-family structural survey is a family report PDF and a full data table. The report summarizes the structural landscape of the gene, separating true mutants from same-sequence copies and wrong domains.