
Undeclared mutations in Protein Data Bank (PDB) entries are a critical source of data integrity errors in structural biology. You can identify these hidden sequence differences by performing a residue-level alignment between the deposited structure and its reference wild-type sequence, rather than relying solely on the entry title or mutation labels. This guide explains how to systematically audit structural data to uncover silent mutations, ensuring your downstream analyses are built on accurate geometric and sequence foundations. For additional details, review the Protein Structure Analyzer.
Introduction to Structural Data Integrity
Structural biology relies on the assumption that deposited data accurately reflects the biological system under study. However, the Protein Data Bank contains millions of entries where the deposited sequence may differ from the canonical wild-type sequence without explicit declaration in the entry metadata. These discrepancies can arise from cloning artifacts, silent mutations, or mislabeled constructs. For researchers using these structures for drug design or functional analysis, an undeclared mutation can completely invalidate the results. Morphogenesis Analytics provides computational tools to audit these entries, ensuring that the structural data you use is consistent with the sequence you expect. For additional details, review the .
Engineered Mutation Detection
Engineered mutation detection is the process of identifying amino acid substitutions in a deposited structure that are not explicitly listed in the entry's mutation labels or title. This is distinct from natural polymorphisms, as engineered mutations are typically introduced for experimental purposes, such as stabilizing a construct or creating a disease model. The core challenge is that the PDB format allows for sequence differences to be present in the coordinate file without corresponding SEQRES or MUTATION records. By comparing the observed residues in the structure against a reference sequence, we can flag any position where the deposited residue does not match the reference. This residue-level evidence is critical for determining whether a structure represents the intended protein variant. For additional details, review the Customer Experience.
Why Labels Fail
Deposited mutation labels are often incomplete or inconsistent. A researcher might introduce a mutation to improve crystallization but forget to update the metadata. Alternatively, a structure might be deposited as a wild-type protein, but the construct used for expression contained a silent mutation that resulted in an amino acid change. These silent mutations are invisible to standard label-based searches. Therefore, relying solely on the text fields in a PDB entry is insufficient for rigorous structural analysis. A comprehensive audit must inspect the actual atomic coordinates and sequence data. For additional details, review the Frequently Asked Questions.
Residue-Level Evidence
Understanding Distinct Evidence Layers
Structural data integrity is not a binary state. It is composed of multiple distinct evidence layers that must be evaluated separately. Geometry, sequence identity, deposited mutation labels, and pathogenicity annotations are distinct kinds of evidence and are reported separately. Conflating these layers leads to misinterpretation. For instance, a structure may have perfect geometry but a sequence that differs from the reference. Conversely, a structure may have a declared mutation that is not actually present in the coordinates. By separating these layers, we provide a clear and unambiguous picture of the data's quality. For additional details, review the About.
Geometry vs. Sequence
Geometric distance from a reference describes geometric difference, not biological function, mutation impact, pathogenicity, cancer severity or drug sensitivity. A structure can be geometrically similar to a reference even if it contains several mutations. This is because the overall fold of a protein is often robust to point mutations. Therefore, geometric similarity alone is not a reliable indicator of sequence identity. Researchers must always check the sequence layer independently of the geometric layer.
Pathogenicity Annotations
Pathogenicity annotations, such as those from AlphaMissense, are third-party predictions and are not generated by this platform. These annotations provide a separate layer of evidence regarding the potential functional impact of a mutation. However, they are predictions, not observations. A mutation may be predicted to be pathogenic, but the deposited structure may not actually contain that mutation. By keeping these layers distinct, we prevent the conflation of predictive models with observed structural data.
Reference Alignment and Sequence Identity
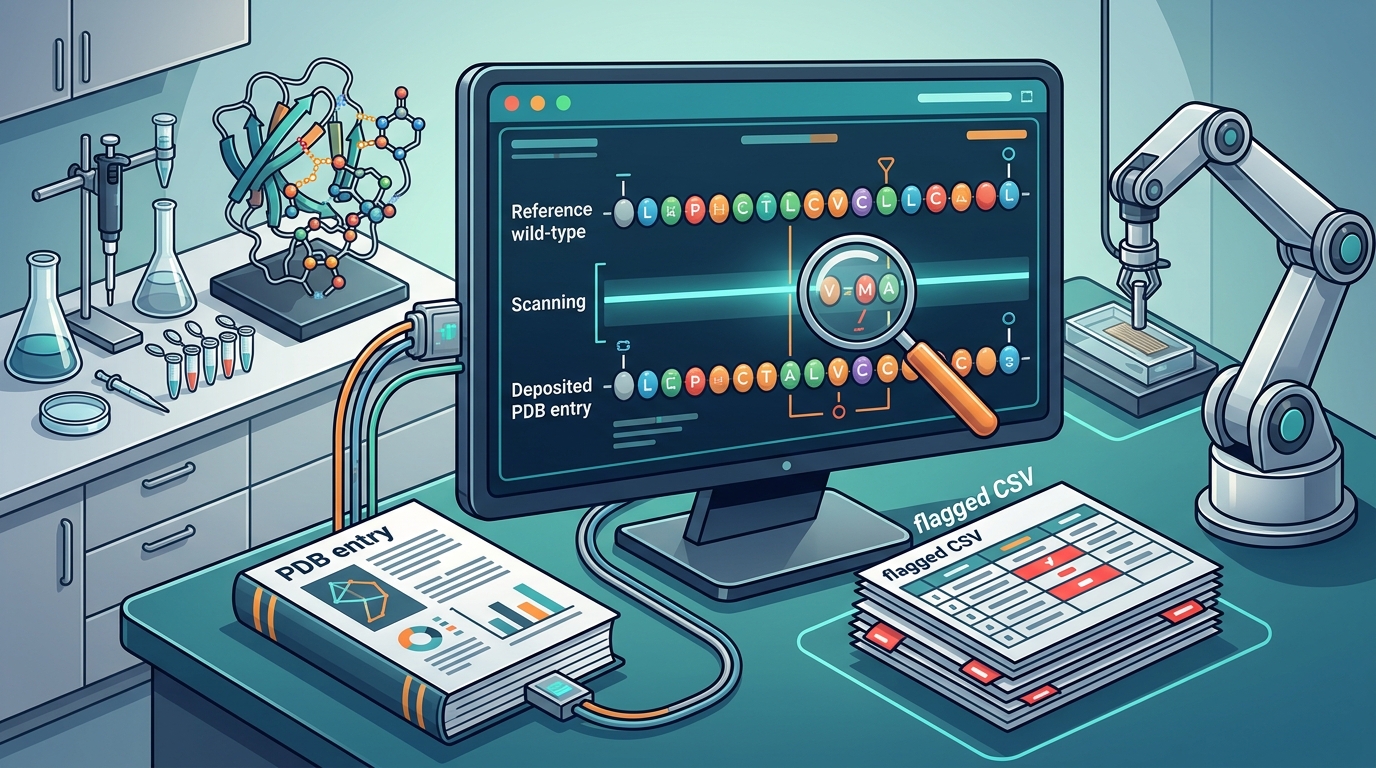
Reference alignment is the foundational step in detecting undeclared mutations. It involves aligning the sequence of the deposited structure against a canonical reference sequence, such as the wild-type protein from UniProt. This alignment identifies all positions where the sequences differ. The sequence identity is then calculated as the percentage of matching residues. A high sequence identity does not guarantee the absence of mutations, as a single critical mutation can have a profound impact. Therefore, the alignment must be inspected position by position, not just summarized by a single identity score.
Choosing the Right Reference
Selecting the correct reference sequence is crucial. For cancer genes, the reference is often the wild-type sequence from a specific isoform. Using the wrong isoform can lead to false positives, where natural isoform differences are mistaken for mutations. Therefore, the reference must be carefully chosen to match the construct used for expression. This requires knowledge of the experimental context, which is often not fully documented in the PDB entry. By providing tools to test against multiple references, we help researchers identify the most likely intended construct.
Handling Indels
Insertions and deletions (indels) are another form of sequence difference that can be undeclared. Indels can shift the reading frame or alter the protein's structure significantly. Detecting indels requires a more complex alignment algorithm than simple point mutation detection. Our tools handle indels by reporting the length and position of the insertion or deletion, along with the surrounding sequence context. This allows researchers to assess the potential impact of the indel on the protein's function. according to wwPDB Format version
Conformational Ambiguity and Geometric Distance
Conformational ambiguity arises when a protein can adopt multiple stable shapes. This is a major source of confusion in structural analysis. A structure may appear to differ from a reference due to a conformational change, not a mutation. For example, a protein in an open state may look very different from a protein in a closed state, even if the sequences are identical. This is why geometric distance must be interpreted with caution. A large geometric distance does not necessarily imply a mutation. It may simply reflect a different conformational state.
Conformational States
Differences can arise from conformational state, construct, ligands or binding partners. A protein bound to a ligand may adopt a different shape than the same protein in the absence of the ligand. This is a normal biological phenomenon, not a data error. However, it can be mistaken for a mutation if the researcher is not aware of the conformational change. By providing tools to compare structures region by region, we help researchers distinguish between conformational changes and sequence differences. according to To tell whether
Ligand and Partner Effects
Ligands and binding partners can induce significant structural changes. These changes are often localized to the binding site but can propagate through the protein. This allosteric effect can make two structures of the same protein look very different. Again, this is not a mutation. It is a functional response to binding. By understanding these effects, researchers can avoid misinterpreting conformational changes as sequence errors.
Validation and Verification Protocols
Validation is the final step in the audit process. It involves checking the flagged discrepancies against the original deposition data. A flagged label discrepancy should be checked against the original deposition before concluding the entry is wrong. This is because the PDB entry may contain additional metadata that explains the discrepancy. For example, the entry may note that the construct used for expression contained a mutation that was not listed in the title. By checking the original deposition, we can confirm whether the discrepancy is a data error or a legitimate experimental variation.
Checking Original Deposition
Independent Verification
Results are provided as is, without guarantee of accuracy or completeness. Users are responsible for independent verification. This means that researchers should not rely solely on our tools. They should also check the original papers, the depositor's notes, and other available data. By combining our computational analysis with manual verification, researchers can achieve the highest level of confidence in their data.
Key Takeaways
- Undeclared mutations are a common source of data integrity errors in PDB entries.
- Reliance on entry titles and mutation labels is insufficient for rigorous structural analysis.
- Residue-level alignment against a reference sequence is the most reliable method for detecting mutations.
- Geometry, sequence identity, and pathogenicity annotations are distinct evidence layers that must be evaluated separately.
- Conformational changes and ligand binding can cause geometric differences that are not due to mutations.
- Flagged discrepancies should be verified against the original deposition data before concluding an error.
- AlphaMissense scores are third-party predictions and are not generated by the analysis platform.
- Independent verification is essential for ensuring the accuracy of structural data.
Frequently Asked Questions
What is an undeclared mutation in a PDB entry?
An undeclared mutation is an amino acid substitution in a deposited structure that is not explicitly listed in the entry's mutation labels or title. These mutations can arise from cloning artifacts, silent mutations, or mislabeled constructs.
How can I detect undeclared mutations in a PDB entry?
You can detect undeclared mutations by performing a residue-level alignment between the deposited structure and its reference wild-type sequence. This identifies any positions where the deposited residue does not match the reference.
Why are mutation labels often incomplete?
Mutation labels are often incomplete because researchers may forget to update the metadata when introducing mutations for experimental purposes. Additionally, silent mutations in the expression construct may result in amino acid changes that are not declared in the entry.
What is the difference between geometric distance and sequence identity?
Geometric distance describes the spatial difference between two structures, while sequence identity describes the percentage of matching amino acids. A structure can have high geometric similarity but low sequence identity, or vice versa.
Can conformational changes be mistaken for mutations?
Yes, conformational changes can be mistaken for mutations if the researcher is not aware of the protein's ability to adopt multiple stable shapes. This is why geometric distance must be interpreted with caution. according to To tell whether
What are pathogenicity annotations?
Pathogenicity annotations are predictions of the functional impact of a mutation. These annotations are often generated by third-party tools such as AlphaMissense and are not part of the deposited structural data.
How should I verify a flagged discrepancy?
You should verify a flagged discrepancy by checking the original deposition data, including the full sequence, expression construct, and depositor's notes. This can help resolve apparent errors and confirm the legitimacy of the variation.
Is the analysis provided by Morphogenesis Analytics a clinical diagnostic?
No, the analysis is for research use only. It is not a medical device or clinical diagnostic and must not be used for patient care decisions.
Conclusion
Detecting undeclared mutations in PDB entries is a critical step in ensuring the integrity of structural biology data. By using residue-level alignment and evaluating distinct evidence layers, researchers can uncover hidden sequence differences that would otherwise go unnoticed. Morphogenesis Analytics provides the tools to perform this audit efficiently and accurately. We encourage researchers to use these tools to verify their data before proceeding with downstream analyses. By doing so, you can ensure that your results are built on a solid foundation of accurate structural data.